Microsoft Azure
DRAFT THIS DOCUMENT IS A WORK IN PROGRESS
This guide will help you get up and running with the Apertus models on Microsoft Azure.
Deploying Apertus currently requires a customized vLLM container or environment. Since Apertus 1.5 introduces a novel multimodal architecture for native image and audio processing, the model dependencies are not yet fully merged into upstream vLLM and Transformers releases. The Apertus team provides pre-built Docker images and custom forks of vLLM and Transformers that you can use in the meantime.
The following guide is based on the Azure Samples Swiss LLM Quickstart (MIT license) developed by Francesco Sodano and Dominique Broeglin at Microsoft.
Deploy on an Azure Virtual Machine
This quickstart provides the following support:
- Instructions on how to download the model from Hugging Face.
- Provision suitable Spot instances in your Azure subscription.
- Guidance on how to deploy and serve the model for local inference.
Getting Started
For the Apertus 1.5 8B, we will use the Standard_NC24ads_A100_v4 SKU with 1 GPU in Azure.
| Component | Specification |
|---|---|
| Series | NC_A100_v4 |
| vCPUs | 24 |
| CPU | AMD EPYC 7V13 (Milan) [x86-64] |
| System memory (RAM) | 220 GiB |
| GPUs | 1 × NVIDIA A100 PCIe |
| GPU memory | 80 GB |
| Local temporary disk | 64 GiB (per-size; series range: 64–256 GiB) |
| NVMe local storage | Up to 960 GiB (series) |
| Network bandwidth | Nominal: ~20,000 Mbps (20 Gbps); series supports up to 80,000 Mbps (80 Gbps) |
| NICs | 2 (series range: 2–8) |
For the Apertus 1.5 70B, we will use the Standard_NC96ads_A100_v4 SKU with 4x GPUs in Azure.
| Component | Specification |
|---|---|
| Series | NC_A100_v4 |
| vCPUs | 96 |
| CPU | AMD EPYC 7V13 (Milan) [x86-64] |
| System memory (RAM) | 880 GiB |
| GPUs | 4 × NVIDIA A100 PCIe |
| GPU memory | 4 × 80 GB |
| Local temporary disk | 64 GiB (per-size; series range: 64–256 GiB) |
| NVMe local storage | Up to 3840 GiB (series) |
| Network bandwidth | Nominal: ~20,000 Mbps (20 Gbps); series supports up to 80,000 Mbps (80 Gbps) |
| NICs | 8 (series range: 2–8) |
These SKUs are available only on a subset of Azure regions. Please check the availability on the Product Availability by Region page.
Prerequisites
Before you begin:
- Azure CLI installed and logged in:
az login - Set your subscription:
az account set --subscription <SUBSCRIPTION_ID> - Sufficient quota for the selected GPU SKUs in your region
- A Hugging Face account and token (for model download)
- SSH key available (the deploy script can generate one if missing)
Environment Variables
Add the following environment variables:
LABELis a name that will be re-used for various Azure resources, such as resource groups and virtual machines.LOCATIONis the Azure region to which your resources will be deployed. Be sure that you choose an Azure region where the SKU is available and you have quota for it.
In this example we used the Switzerland North datacenter.
export LABEL=swiss-llm-001
export LOCATION=switzerlandnorth
Check GPU Quota
Based on the location you choose, you can check the current quota with the following:
az vm list-usage --location "${LOCATION}" --query "[?name.value=='StandardNCADSA100v4Family']" -o tableCheck that the Limit value is at least 24 for Standard_NC24ads_A100_v4 (Apertus 8B) and at least 96 for Standard_NC96ads_A100_v4 (Apertus 70B).
Clone the Repository
git clone https://github.com/Azure-Samples/swiss-llm-quickstart
cd swiss-llm-quickstart/azure-virtual-machine
Deploy the Virtual Machine
Based on the model you would like to install, run one of the following scripts.
For Apertus-v1.5-8B:
./deploy.shFor Apertus-v1.5-70B:
./deploy.sh --sku Standard_NC96ads_A100_v4If you want to deploy a VM for Apertus-v1.5-70B in a different region and with a different name, you can run:
./deploy.sh --location swedencentral --name vm-swiss-llm-002 --sku Standard_NC96ads_A100_v4Virtual Machine Installation
You should now be able to access the virtual machine with the SSH command displayed after executing the deploy script:
ssh azureuser@__public_ip_address__When connected, you need to install the correct NVIDIA drivers.
Ubuntu packages NVIDIA proprietary drivers. Those drivers come directly from NVIDIA and are simply packaged by Ubuntu so that they can be automatically managed by the system.
The following init.sh script, executed through cloud-init after VM creation, will:
- Install the
ubuntu-driversutility - Install the latest NVIDIA drivers
- Download and install the CUDA toolkit from NVIDIA
- Update
PATH - Reboot the VM
Note: The script may take a few minutes to complete.
After the VM has rebooted, verify the driver and toolkit installation:
nvidia-smi
nvcc --version || echo "nvcc not found; ensure CUDA toolkit installed"
Prepare the Python Environment
Information for Apertus 1.5 — We are currently working on adding support for our models to upstream vLLM and Transformers releases. See the Docker deployment section below as an alternative to a manual Python environment.
Log in again into the VM and execute the following commands to install uv and prepare a Python environment:
curl -LsSf https://astral.sh/uv/install.sh | sh
source ~/.bashrc
uv init
Install PyTorch:
cat >> pyproject.toml <<'EOF'
[[tool.uv.index]]
name = "pytorch-cu128"
url = "https://download.pytorch.org/whl/cu128"
explicit = true

[tool.uv.sources]
torch = [
  { index = "pytorch-cu128", marker = "sys_platform == 'linux' or sys_platform == 'win32'" },
]
torchvision = [
  { index = "pytorch-cu128", marker = "sys_platform == 'linux' or sys_platform == 'win32'" },
]
EOF
uv add torch torchvision
Install the Apertus-modified vLLM and Transformers from the Swiss AI forks, along with the remaining dependencies:
uv add "vllm @ git+https://github.com/swiss-ai/vllm.git"
uv add "transformers @ git+https://github.com/swiss-ai/transformers.git"
uv add git+https://github.com/nickjbrowning/XIELU
uv add "huggingface_hub[cli]" hf_transfer
uv add rich
uv add flashinfer-python
uv add fastsafetensors
Log in to Hugging Face Hub and download the model.
For Apertus-v1.5-8B:
uv run hf auth login
uv run hf download swiss-ai/Apertus-v1.5-8B
For Apertus-v1.5-70B:
uv run hf auth login
uv run hf download swiss-ai/Apertus-v1.5-70B
Run the Model with vLLM
We will use vLLM to run the model.
For Apertus-v1.5-8B:
uv run vllm serve swiss-ai/Apertus-v1.5-8B \
  --chat-template-content-format string \
  --gpu-memory-utilization 0.6 \
  --max-model-len 262144 \
  --enable-auto-tool-choice \
  --tool-call-parser apertus
For Apertus-v1.5-70B:
uv run vllm serve swiss-ai/Apertus-v1.5-70B \
  --chat-template-content-format string \
  --tensor-parallel-size 4 \
  --gpu-memory-utilization 0.8 \
  --max-model-len 262144 \
  --enable-auto-tool-choice \
  --tool-call-parser apertus
Depending on your hardware, you may need to adjust --tensor-parallel-size, --gpu-memory-utilization, and --max-model-len (e.g. lower --max-model-len if you run out of memory). On some hardware configurations, CUDA Graph capture may fail with --tensor-parallel-size > 1 due to the fused all-reduce RMS optimization. If this occurs, launch vLLM with --compilation-config.pass_config.fuse_allreduce_rms false.
Thinking Mode
To enable thinking mode, set --reasoning-parser and --default-chat-template-kwargs.enable_thinking as shown below. The tool-call flags are intentionally omitted: tool calling is unsupported in thinking mode, so we don’t recommend combining the two.
For Apertus-v1.5-8B:
uv run vllm serve swiss-ai/Apertus-v1.5-8B \
  --served-model-name swiss-ai/Apertus-v1.5-8B-thinking \
  --chat-template-content-format string \
  --gpu-memory-utilization 0.6 \
  --max-model-len 262144 \
  --reasoning-parser apertus \
  --default-chat-template-kwargs.enable_thinking true
For Apertus-v1.5-70B:
uv run vllm serve swiss-ai/Apertus-v1.5-70B \
  --served-model-name swiss-ai/Apertus-v1.5-70B-thinking \
  --chat-template-content-format string \
  --tensor-parallel-size 4 \
  --gpu-memory-utilization 0.8 \
  --max-model-len 262144 \
  --reasoning-parser apertus \
  --default-chat-template-kwargs.enable_thinking true
Test the Model
To test the model, open an additional SSH terminal on the VM (keep the first one running the server) and run the following command. If you prefer to call from your local machine, you can use SSH port forwarding: ssh -L 8000:localhost:8000 azureuser@<ip>.
For Apertus-v1.5-8B:
curl http://localhost:8000/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{
      "model": "swiss-ai/Apertus-v1.5-8B",
      "messages": [
          {"role": "system", "content": "You are a helpful assistant."},
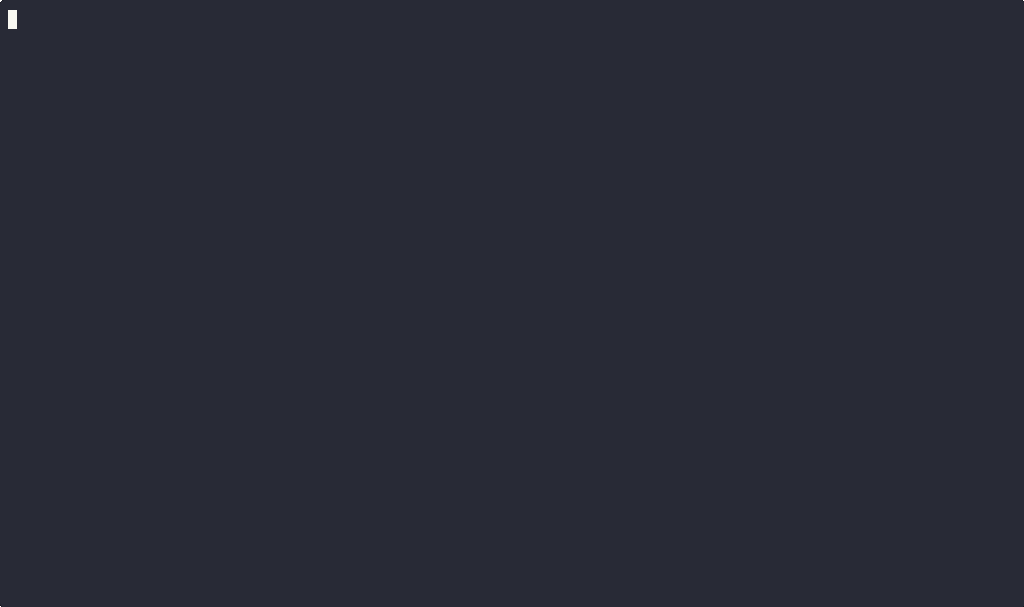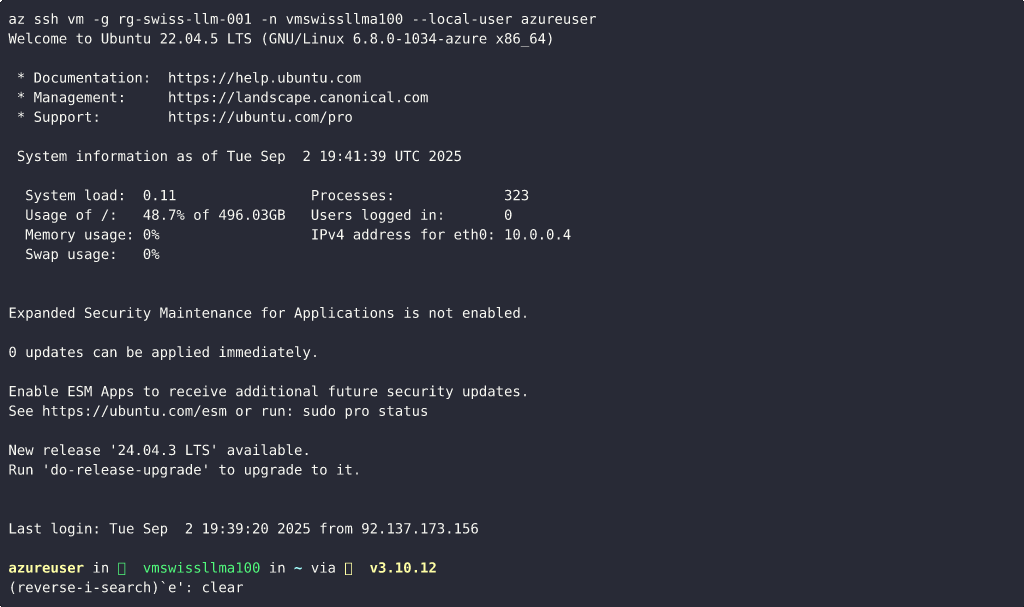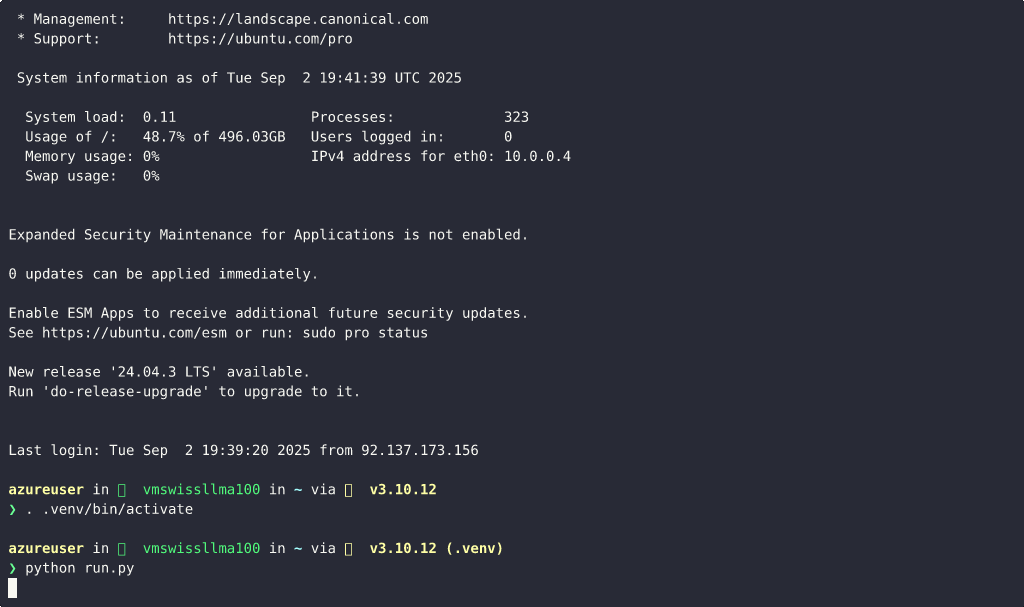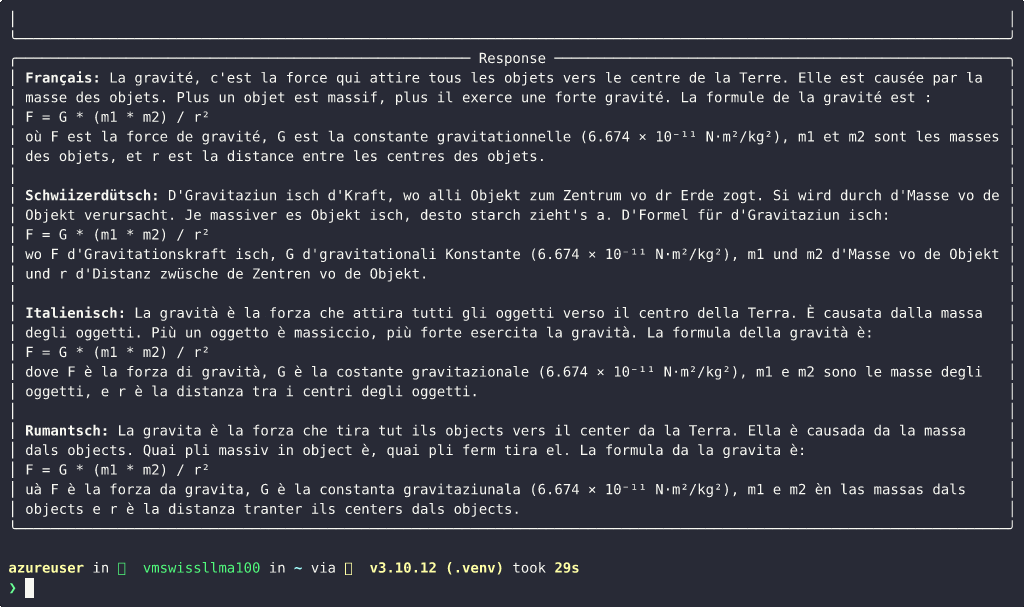
          {"role": "user", "content": "Give a simple explanation of what gravity is for a high school level physics course with a few typical formulas. Use lots of emojis and do it in French, Swiss German, Italian and Romansh."}
      ]
  }'
For Apertus-v1.5-70B:
curl http://localhost:8000/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{
      "model": "swiss-ai/Apertus-v1.5-70B",
      "messages": [
          {"role": "system", "content": "You are a helpful assistant."},
          {"role": "user", "content": "Give a simple explanation of what gravity is for a high school level physics course with a few typical formulas. Use lots of emojis and do it in French, Swiss German, Italian and Romansh."}
      ]
  }'
If the installation completes successfully, you should see something similar to this:

Clean Up
To clean up all the resources created by this sample, delete the resource group used during deployment.
az group delete --name "rg-${LABEL}" --yes --no-waitOr if you want to clean up the virtual machine and attached resources only, you can run:
RESOURCE_GROUP="rg-${LABEL}"
VM_NAME="vm-swiss-llm-001"

az resource update \
  --resource-group "${RESOURCE_GROUP}" \
  --name "${VM_NAME}" \
  --resource-type virtualMachines \
  --namespace Microsoft.Compute \
  --set properties.storageProfile.osDisk.deleteOption=delete

az vm delete \
  --resource-group "${RESOURCE_GROUP}" \
  --name "${VM_NAME}" \
  --force-deletion
Cost Estimation
Pricing varies per region and usage, so it isn’t possible to predict exact costs for your usage. However, you can try the Azure pricing calculator for the resources below.
⚠️ To avoid unnecessary costs, remember to take down your resources if they are no longer in use.
You can reduce VM cost by deallocating the VM when not in use. This will stop the VM and you will not be charged for compute resources, but you will still be charged for storage.
az vm deallocate -g MyResourceGroup -n MyVmNameNotes
- Spot instances: The deploy scripts use Spot priority by default (
--priority Spot). Spot VMs are lower-cost but can be evicted. For uninterrupted runs, switch to regular priority by removing that flag or setting--priority Regular. - Server lifetime: Consider running
vllm serveinsidetmuxorscreento avoid interruption when the SSH session closes.
Deploy with a Docker Container
This quickstart provides the following support:
- Instructions on how to build and run the vLLM container for Apertus 1.5 8B and 70B.
- You can build and use this container on your local machine or on a cloud VM with capable GPU support (e.g. Azure, AWS, GCP).
- You can use the container on any Azure compute service (Azure Container Instances, Azure Kubernetes Service, Azure Virtual Machines, Azure Container Apps) or on other providers (local, AWS, GCP, etc.).
The Apertus team provides a pre-built Docker image with all Apertus 1.5 dependencies pre-installed. The image is available in the GitHub Container Registry for both amd64 and arm64 architectures.
Pull the image that matches your architecture:
# amd64 architecture
docker pull ghcr.io/swiss-ai/vllm_apertus_1.5_release:latest-amd64

# arm64 architecture
docker pull ghcr.io/swiss-ai/vllm_apertus_1.5_release:latest-arm64
The source Dockerfile used to build the image is available in the model-launch repository.
If you prefer to build the image yourself, see Build the Docker Image below.
Prerequisites
Before you begin:
- Docker installed on your local machine or cloud VM. Follow the instructions for your platform:
- An NVIDIA GPU with the appropriate drivers installed.
- NVIDIA Container Toolkit installed to enable GPU support in Docker.
- A Hugging Face account and an access token with permission to download the Apertus models. You can create a token in your Hugging Face account settings under “Access Tokens”.
- (Optional) If you are using an Azure VM, ensure that the VM is an N-series instance with GPU support. Follow the instructions to set up the NVIDIA drivers on your Azure VM: Azure N-series GPU driver setup for Linux - Azure Virtual Machines | Microsoft Learn
Build the Docker Image
From the root of the model-launch repository, build the Docker image:
git clone https://github.com/swiss-ai/model-launch
cd model-launch
docker build -f images/vllm_apertus_1.5_release/Dockerfile -t apertus-vllm .
Run the Docker Image
The Docker image is configured to run vLLM with the Apertus 1.5 8B model by default in chatbot optimization with the following default parameters.
| Parameter | Default Value |
|---|---|
MODEL_ID | swiss-ai/Apertus-v1.5-8B |
GPU_MEMORY_UTILIZATION | 0.6 |
MAX_MODEL_LEN | 262144 |
TENSOR_PARALLEL_SIZE | 1 |
ENABLE_AUTO_TOOL_CHOICE | true |
TOOL_CALL_PARSER | apertus |
CHAT_TEMPLATE_CONTENT_FORMAT | string |
For the meaning of the parameters, see the vLLM Serve Parameters.
To run the container with the default parameters:
docker run --gpus all -p 8000:8000 \
  -e HF_TOKEN=your_token_here \
  -v ~/.cache/huggingface:/home/appuser/workspace/hf-home \
  apertus-vllm
The additional parameters for docker run are the following:
-e HF_TOKENgives the container the capability to download the model from Hugging Face.-v ~/.cache/huggingface:/home/appuser/workspace/hf-homeis the mapping of the Hugging Face cache from the host to the container. The Hugging Face cache uses theHF_HOMEenvironment variable, which is set to/home/appuser/workspace/hf-homein the container.
To run the container with the Apertus 1.5 70B model, you need to override some of the default parameters. This is an example command to run the container with the 70B model based on a 4 × A100 80 GB GPU VM (Standard_NC96ads_A100_v4 in Azure):
docker run --gpus all -p 8000:8000 \
  -e HF_TOKEN=your_token_here \
  -e MODEL_ID=swiss-ai/Apertus-v1.5-70B \
  -e TENSOR_PARALLEL_SIZE=4 \
  -e GPU_MEMORY_UTILIZATION=0.8 \
  -e MAX_MODEL_LEN=262144 \
  -v ~/.cache/huggingface:/home/appuser/workspace/hf-home \
  apertus-vllm
Run the Docker Image Interactively
To run the container interactively, use the following command:
docker run --gpus all -it --rm --user root --entrypoint bash apertus-vllmThis will give you a bash shell inside the container. You can then run the vllm serve command manually with your desired parameters.